Felix Frank · 17 September 2026
Leveraging Log File Analysis to Identify Indexing Gaps in Large Stone Inventory Websites
Log file analysis serves as a direct method for examining how search engine crawlers interact with extensive product catalogs on stone inventory websites, where thousands of individual stone listings often span multiple categories and geographic regions. Data from server logs reveals crawl frequency, response codes, and user-agent patterns that indicate which pages receive attention and which ones remain overlooked, allowing site operators to pinpoint indexing gaps without relying solely on third-party tools. In large inventories, gaps frequently arise when crawlers skip deep product pages or encounter repeated server errors that block access to specific stone varieties.
Core Elements of Log File Examination
Server logs record every request made to a website, including timestamps, requested URLs, HTTP status codes, and the identity of the visiting bot or user. Analysts parse these entries to separate legitimate crawler activity from other traffic, focusing on patterns that show how often Googlebot, Bingbot, or other engines visit stone detail pages versus category overviews. Research indicates that high-volume sites with dynamic inventory updates see crawlers prioritize recently modified content, which leaves older listings vulnerable to reduced visibility if updates occur infrequently.
Those who study web infrastructure note that combining log data with sitemap submissions helps confirm whether submitted URLs match actual crawler behavior. For stone suppliers managing inventories across multiple warehouses, logs often highlight regional differences in crawl rates, such as slower discovery of products stored in secondary locations. Evidence from industry reports shows that sites exceeding 50,000 product pages experience indexing shortfalls when crawl budgets are not allocated efficiently across similar-looking stone entries.
Applying Analysis to Stone Inventory Structures
Large stone inventory platforms typically organize content through faceted navigation adn attribute-based filtering that generates numerous URL combinations for the same physical items. Log examination identifies when crawlers treat these variations as duplicate content or when they abandon deep links that lead to individual stone specifications. Observers have documented cases where parameter-heavy URLs for color, size, or origin attributes receive inconsistent visits, resulting in entire subsets of inventory failing to appear in search results.
September 2026 brought updates to crawler behavior documentation from major engines that emphasized improved handling of inventory-driven sites, yet many operators still rely on manual log reviews to detect gaps before they compound. Analysts compare request volumes against total page counts to calculate crawl efficiency ratios, revealing sections where stone listings sit unvisited for weeks at a time.
Detecting Specific Indexing Shortfalls
Indexing gaps become visible when logs show repeated 404 responses for stone product URLs or when successful crawls fail to produce corresponding entries in search engine indexes. People managing these sites cross-reference log timestamps with index coverage reports to isolate pages that receive visits but never achieve indexed status due to thin content signals or technical barriers. Data indicates that stone inventory sites using JavaScript-rendered details encounter additional hurdles, as crawlers may record the initial HTML request without confirming full content rendering.
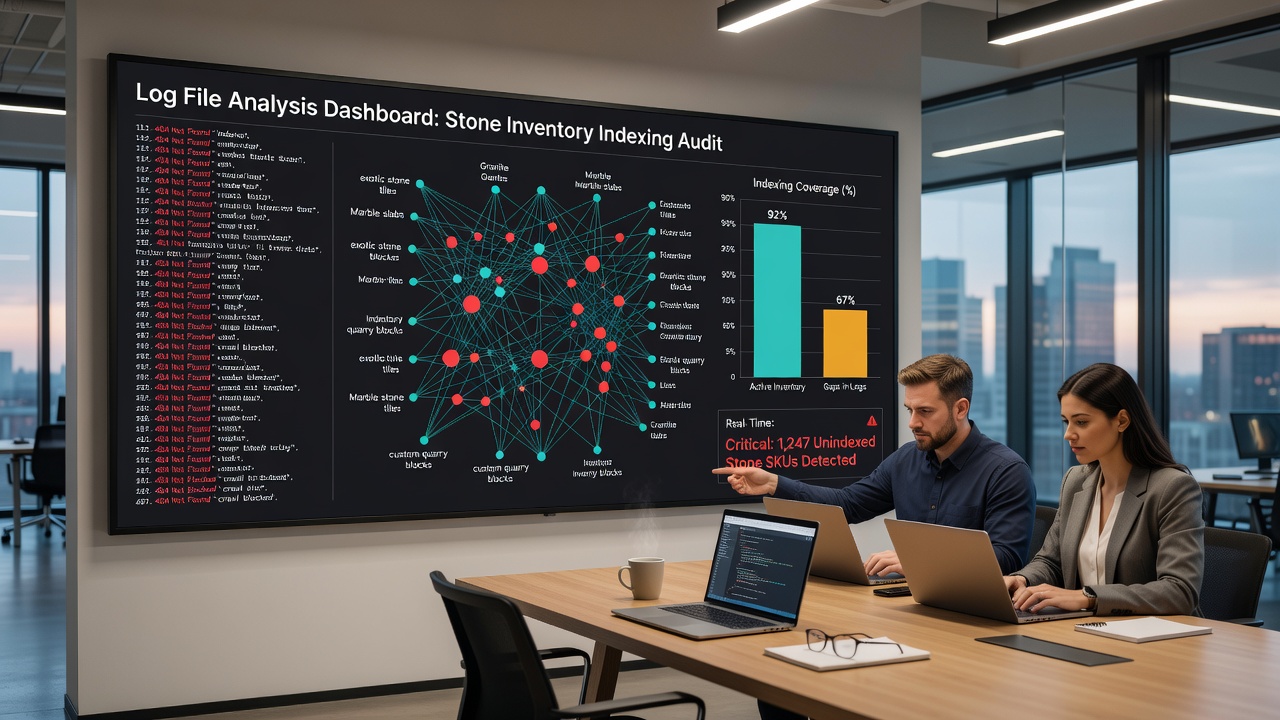
Researchers at academic institutions have examined similar retail environments and found that systematic log segmentation by user-agent and response code accelerates identification of problem areas. One study revealed that grouping entries by date ranges exposes seasonal crawl surges that coincide with inventory uploads, helping teams time content refreshes to match engine visitation peaks. Sites that implement these segmentation practices report faster resolution of gaps affecting high-value stone categories.
Practical Implementation Steps
Teams begin by exporting raw log files from web servers and filtering them through scripts that isolate crawler activity based on known user-agent strings. Subsequent analysis maps requested paths against the full inventory database to flag URLs that exist in the catalog yet never appear in the logs. External verification through tools provided by search engines confirms whether unlogged pages suffer from robots.txt restrictions or server-side rendering failures that prevent proper indexing.
According to documentation from the World Wide Web Consortium on HTTP access patterns, consistent monitoring of status code distributions prevents small errors from escalating into widespread indexing losses across product-heavy domains. Operators further integrate log insights with structured data markup to strengthen signals that crawlers use when deciding which stone pages merit inclusion in results.
Conclusion
Log file analysis delivers measurable evidence of crawler behavior that directly informs strategies for closing indexing gaps in expansive stone inventory websites. By tracking request patterns, response outcomes, and coverage discrepancies over time, operators maintain visibility for the full range of listings that support business operations. Continued refinement of these techniques aligns site architecture with evolving crawler priorities, ensuring comprehensive representation of available stone products in search environments.